
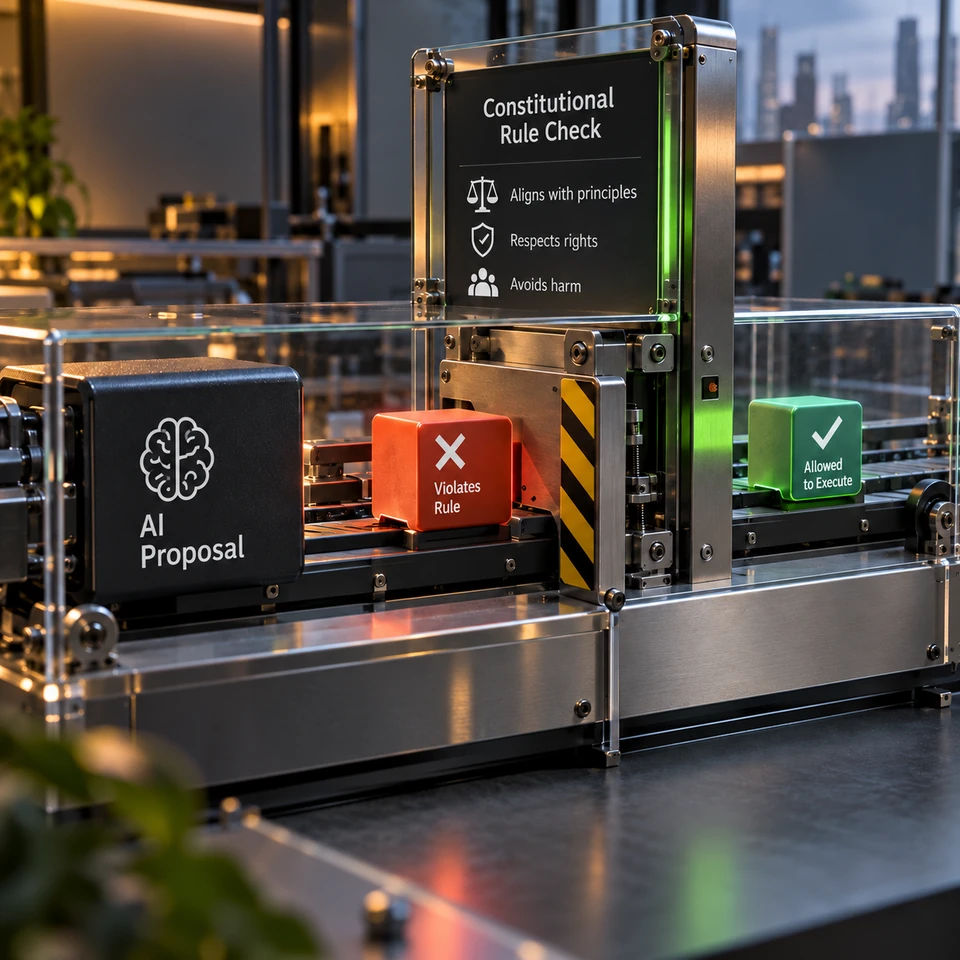
Anthropic's 2022 Constitutional AI research describes model training using a set of principles, with a supervised critique-and-revision phase and reinforcement learning from AI feedback. This article uses organizational policy enforcement at runtime as a separate engineering pattern.
A deployment also needs decisions about who may access data, invoke tools, and approve consequential actions. Enforce the selected boundaries through controls appropriate to the workflow, and record enough context to review how those controls operated.
Training evidence and runtime control evidence answer different questions. Review both for the system's intended use rather than treating a training technique as proof that organizational permissions are enforced.
At a glance
- Constitutional AI is a training method whose effects shape model behavior during use
- Runtime constitutional enforcement is a separate architectural layer that applies policies during production execution
- The two are complementary: training shapes default behavior; runtime enforcement catches what training misses
- A constitutional AI runtime requires three things: a formal constitution, a real-time evaluator, and tamper-evident logging
- Select deployment controls for the system's risks and applicable duties; model alignment does not establish organizational authorization
What Anthropic’s Constitutional AI Actually Does
When Anthropic built Constitutional AI (CAI), the goal was training efficiency and value alignment. Instead of labeling every potentially harmful response with human feedback, they trained the model to critique and revise its own outputs against a list of principles.
Anthropic's research reports results for the methods and evaluations it studied. For a deployment, evaluate the selected model on the intended tasks and failure modes rather than treating the training method as an assurance of current system behavior.
A training constitution does not establish your deployment's approved actions or thresholds. Define those from your own policy and applicable duties, then test the controls at the data and action boundaries. No universal insurance payment threshold follows from Constitutional AI.
Those rules are yours. They change when your business changes. They need to be applied at runtime, per request, and logged with evidence.
For the full details on Anthropic’s approach, see their Constitutional AI research paper.
The Production Gap
Here is the gap in concrete terms:
| Concern | Anthropic CAI (training) | Runtime enforcement (deployment) |
|---|---|---|
| Generic harm avoidance | Training goal; behavior still needs evaluation | Evaluate model behavior in the deployment |
| Organizational-specific rules | Deployment permissions are not established by the training method | Enforce approved permissions at the relevant boundaries |
| Per-request policy evaluation | Per-request control coverage is not established by the training method | Select checks for the actions that need gating |
| Tamper-evident audit records | Record integrity is not established by the training method | Choose integrity controls for review needs |
| Real-time blocking of violations | Blocking of specific tool actions is not established by the training method | Test blocking on the covered execution paths |
| Human escalation for edge cases | Escalation routing is not established by the training method | Assign reviewers and test escalation paths |
| EU AI Act Article 9 risk management | Lifecycle risk management is not established by the training method | Map controls to the applicable risk management duties |
Training can shape default behavior, while deployment controls constrain particular actions. Neither alone guarantees safety; test the interaction, failure paths, and limits of each control.
This is not a criticism of Constitutional AI as a technique — it’s clarifying scope. A model with strong values still needs organizational governance applied at the point of use. The most ethically trained model in the world doesn’t know your specific compliance requirements.
What a Constitutional AI Runtime Looks Like
Runtime constitutional enforcement has three components.
A Formal Constitution
Your organizational constitution is a machine-parseable document that specifies permitted actions, prohibited actions, conditions, thresholds, and escalation triggers. It’s written by humans, reviewed by compliance, and versioned.
Document the policy's identity, review status, action boundaries, and escalation conditions:
policy_identity- Approved policy identifier and version.
review_record- Actual review owner, decision, and effective status.
permitted- Approved action classes and the conditions needed for authorization.
prohibited- Action classes explicitly denied by the approved policy.
escalation- Review conditions and an assigned, authorized reviewer or workflow.
failure_behavior- Documented response to missing context, conflicting rules, unavailable controls, or expired approval.
This constitution is not a prompt. It’s a formal policy document that the runtime evaluator executes against, at every request, in every session.
A Real-Time Evaluator
The evaluator receives an agent action request and checks it against the current constitution. For each action, it determines: is this permitted under the current conditions? Does it meet the threshold for escalation? Is it outright prohibited?
The evaluator must operate synchronously — it cannot be an async monitoring process that catches violations after the fact. Enforcement means interception before execution.
For a payment workflow, compare the requested action with the approved authorization rule. Hold execution when review is required, and test that alternate execution paths cannot bypass the decision.
Tamper-Evident Logging
Record the policy version, evaluated action, verdict, and context necessary for review. Select integrity controls for the threat model; signatures and hash chains are options, not universal statutory requirements. Test whether missing or bypassed evaluations are detectable.
These records can support review of runtime enforcement when they are connected to the executed action and supported by tests of the control path. A signature authenticates recorded content under key-trust assumptions; it does not by itself prove that enforcement occurred.
event_id- Identifier assigned to the actual event and used to correlate its records.
timestamp- Recorded event time, with the clock source and precision documented.
action_class- Action category from the approved taxonomy.
actor_id- Identity responsible for the actual request, linked to its access context.
policy_version- Approved policy version actually used for the evaluation.
policy_reviewed- Reference to the policy's actual review record.
verdict- Recorded outcome of the control evaluation and its rationale.
evidence_ref- Access-controlled reference to the supporting evidence.
approval_required- Whether the applicable rule requires approval for this action.
approval_record- Actual reviewer, decision, context reviewed, and validity where approval is required.
reversal_handle- Available, tested recovery path, or a documented absence of one.
execution_status- Observed execution state linked to the downstream result.
integrity_metadata- Verification information for the selected integrity controls, if used; it does not establish event truth or completeness.
Why Training Alone Is Insufficient for Production
Three scenarios illustrate why training-time values don’t replace runtime enforcement.
Policy change: update the applicable rules through review, versioning, and tests before release. A runtime policy update may avoid model retraining, but it still needs validation, authorization, and a rollback plan.
Scenario 2: Edge case exploitation. A model trained on general principles can be prompted into behaviors that comply with training but violate specific organizational policy. A user who knows your agent well enough can find the edges. Runtime enforcement catches these at evaluation time regardless of how the prompt was crafted.
Scenario 3: Audit evidence. A regulator asks for evidence that your agent operated within policy during a specific period. Training artifacts (model weights, training logs) don’t answer this question. Runtime records — evaluations, decisions, policy references — do. Evidence of what happened at deployment time requires logging at deployment time.
Implementing Constitutional AI Runtime Enforcement
The implementation sequence, in order:
-
Write the constitution. Document your agent’s permitted actions, prohibited actions, escalation conditions, and the compliance rationale for each. Get it reviewed. Version it.
-
Build or integrate the evaluator. The evaluator can be a rule engine (for deterministic policies), a secondary LLM check (for semantic policies), or a hybrid. Most production systems use a rule engine for speed and auditability, with LLM spot-checks for complex semantic judgments.
-
Instrument the evidence ledger. Capture the relevant control decisions and their connection to execution. Choose access, retention, and integrity controls, and verify exports independently where the review needs it.
-
Implement escalation. Define the routing for ESCALATE decisions. This requires a human review interface — a queue, a notification system, and a way to record the human’s decision and return it to the agent flow.
-
Test against adversarial inputs. Constitutional rules need adversarial testing: what prompts attempt to bypass them? What edge conditions trigger unexpected PERMIT decisions? Run these before go-live.
For horizontal governance coverage, this runtime enforcement approach integrates with the broader EU AI Act requirements covered in our Article 9 continuous risk management guide.
FAQ
Q: Can I use the model’s training constitution (Claude’s, GPT-4’s) instead of writing my own?
Use model training information to understand the model's intended behavior, then specify your deployment's authority and constraints. These may be enforced by existing access controls, tool permissions, approval workflows, or additional runtime checks selected for the risk; a new layer is not automatically required.
Q: How do you handle constitutional rules that conflict?
Rule conflicts are a real design problem. The constitution must include explicit priority ordering: when rule A and rule B conflict, which wins? A well-designed constitution anticipates common conflicts and resolves them explicitly. When a conflict is genuinely unresolvable at evaluation time, the correct default is escalation — route to a human, don’t guess.
Q: Does this work with multi-agent systems?
Yes, and it’s especially important in multi-agent architectures. Each agent in a pipeline needs its own governance scope, and the accountability layer must track the full chain of authorizations across agents. An action authorized at the entry agent does not automatically authorize downstream agents to take subsequent actions — each link in the chain needs its own evaluation.
Q: How often should the constitution be reviewed?
At minimum: after any regulatory change that affects your agent’s domain, after any significant change to the agent’s scope or capabilities, and on a fixed schedule (quarterly for most regulated industries, monthly for high-risk deployments). Version each review with the reviewer’s identity and the date.
Q: What happens if the evaluator goes down?
Fail-safe default: block all actions until the evaluator is restored. A system that defaults to PERMIT when its governance layer is unavailable has inverted its risk model. Operational continuity is a real concern — build for high availability — but the degraded mode must be safe, not permissive.
By Nikola Kovtun, founder of Infracortex AI Studio. We implement constitutional AI runtime enforcement for production agent stacks — formal constitutions, synchronous evaluators, Ed25519-signed evidence ledgers. Book a discovery call to discuss your specific architecture.
See also: What Is an AI Agent Accountability Layer? | Why Your AI Agent Logs Won’t Pass an Audit | Why Runtime is Commodity and Governance is the Moat